Machine Learning

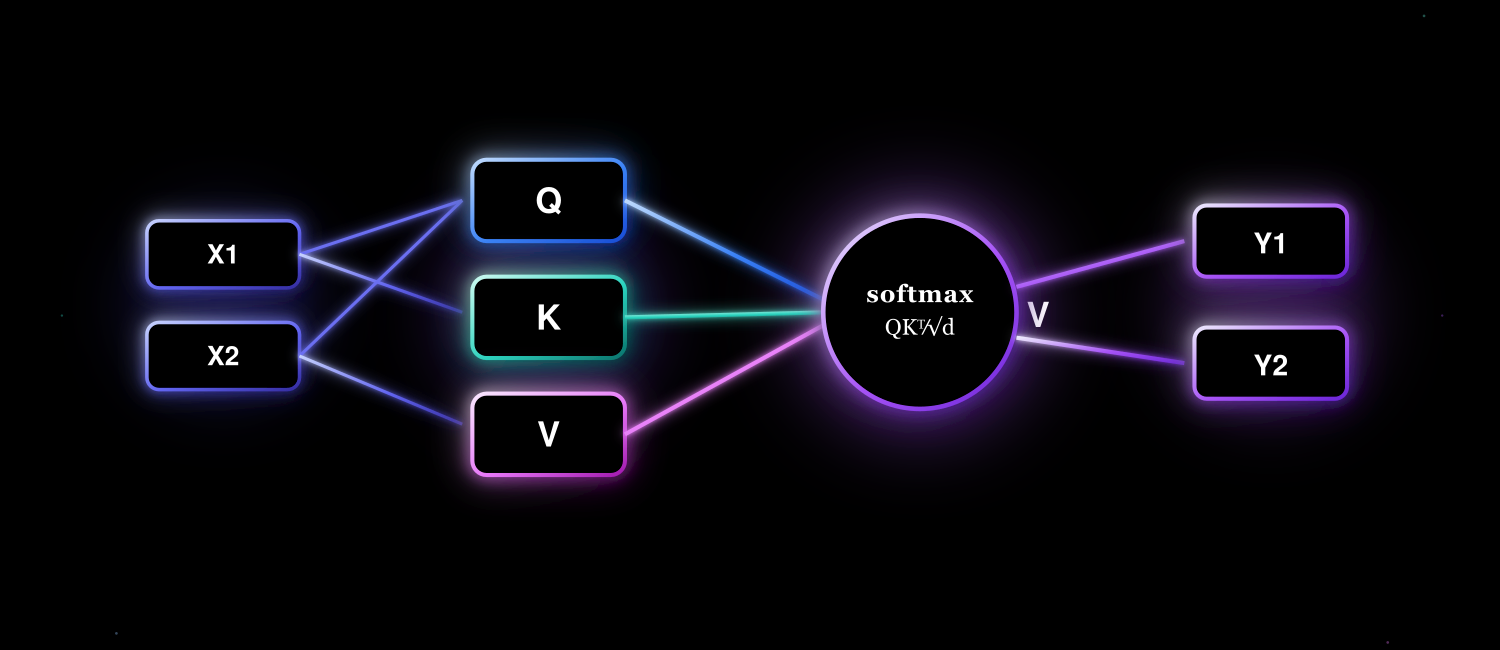
abstract overview of single_head attention
Machine Learning

Understanding Single-Head Attention in Transformers

To understand transformers, you must understand attention.

Many explanations focus on the how rather than the why, making terms like queries, keys, and the underlying math feel arbitrary. You can memorize the attention formula and still have no idea why it actually works. But once you grasp the core intuition behind each step, attention becomes easy to remember and reason about.

In this article, we’ll explore both the how and the why.

Calculus, Machine Learning, Math

Understanding the Softmax Function Derivative

This article discusses the derivative of the softmax function, providing an introductory example suitable for readers with a basic understanding of single-variable calculus. It outlines the mathematical principles necessary for computing this derivative and presents a concise expression for the softmax function’s Jacobian matrix, showcasing its application in probability distributions.

The directional derivative.
Calculus, Machine Learning, Math

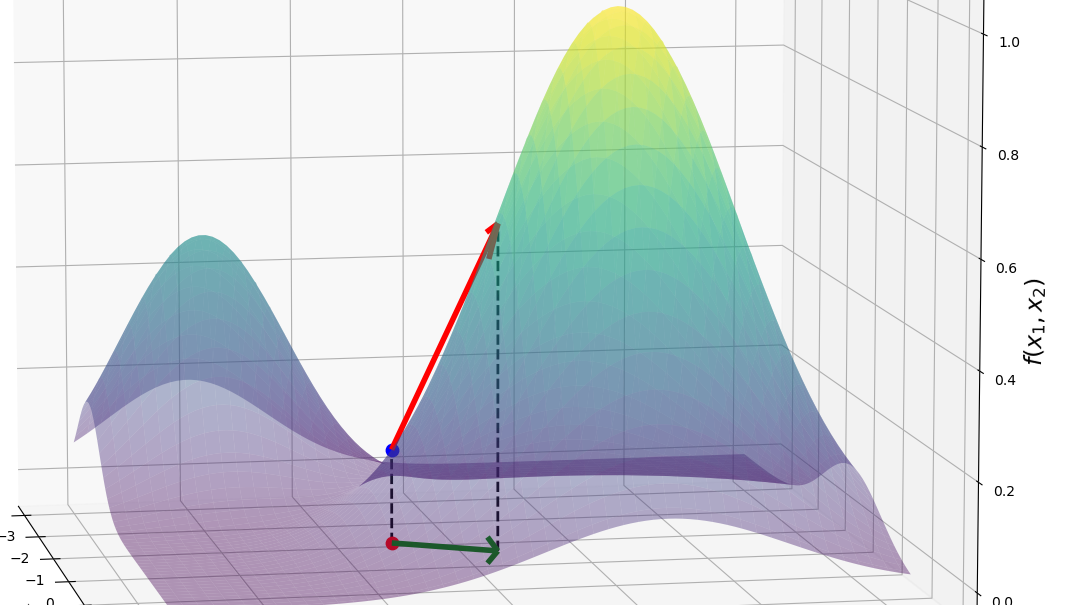
Understanding the Directional Derivative and the Gradient

1 Introduction Understanding how functions change in different directions is crucial in many fields. For example in the context of neural networks where gradients are used to update weights during the training process. In this article, we will explore the concepts of the directional derivative and the gradient, and we will demonstrate their relationship through

Machine Learning

The Sigmoid and its Derivative

The sigmoid function, \(\sigma(x)\), is also called the logistic function, or expit [1]. It is the inverse of the logit function. Its function definition is: \[ \sigma(x) = \frac{1}{1+e^{-x}} \tag{1}\] Let’s get familiar by plotting this function first: And just to be complete, here is the python code that produced the above plot: We see

Machine Learning

What is a Logit?

The term logit has different meanings in math and in the TensorFlow library. In TensorFlow it means “Per-label activations, typically a linear output. These activation energies are interpreted as unnormalized log probabilities.” What this means is: the logits are the vector you get as output of the last layer of your neural network. It is

Scroll to Top
Cookie Consent with Real Cookie Banner